
Match Rate
Updated April 2026
Match Rate Explained
Matching coverage divides accepted input records by the eligible input records tested against a specified reference source. A single benchmark cannot describe NPI identity matching, email append, phone append, and technology detection because each field uses different source coverage, normalization rules, and evidence thresholds. Report the numerator, denominator, unresolved records, and acceptance rule beside each calculation.
Why Match Rate Matters for Healthcare Data
A percentage without its denominator and acceptance rule can hide weak evidence. Buyers need to know whether a match means an exact NPI, a probable name-and-address link, a deliverable business email, or a technology signal observed on a current website. Field-level outcomes make those differences visible and keep unresolved rows out of the accepted count.
Real-World Example
Illustrative workflow: a data team freezes its input file, chooses a dated reference source, and defines exact, probabilistic, rejected, and unresolved outcomes before running the match. It reports each category separately and samples accepted and rejected rows for manual review. The resulting rate describes that specific run, not a general market benchmark.
How should a data team use Match Rate?
Freeze the source file, reference file, matching fields, and acceptance threshold before calculating a match rate. Report exact, probabilistic, rejected, and unresolved outcomes separately, then inspect results by target field. Publish the denominator and the definition of an accepted match beside the resulting percentage.
Which Match Rate fields deserve manual review?
Review matched entity, source, and confidence first. Those fields carry the most weight in a match and create the most damage when stale. Compare the source value with the current practice website or official record, record the date of the check, and keep conflicting evidence visible. A clean-looking row can still connect the right name to the wrong location, organization, or specialty. Identity, affiliation, and contactability should each have their own result.
Where do Match Rate errors enter the workflow?
A frequent error is counting a plausible contact as a verified match. The mistake usually appears during normalization or joining, after the source file has been collected but before the final record is assembled. Preserve source-specific identifiers through each step, compare entity type before joining, and reject matches that depend on name similarity alone. Shared surnames, brand names, and building addresses create false confidence when a pipeline collapses several signals into one score.
Staleness creates a second failure path for Match Rate. A correct historical record may be wrong for a campaign sent today. Save both the source's update date and your own check date. Those dates answer different questions: when the publisher changed the record and when your team confirmed the evidence. Refresh high-change fields such as role, practice affiliation, email, and phone more often than durable identifiers.
How can buyers test Match Rate data before purchase?
A vendor supplying Match Rate should explain source coverage, matching rules, refresh timing, and what happens when sources disagree. Request field-level definitions too. Terms such as current, direct, active, and verified can refer to several different checks. A written acceptance rule makes the project testable: the delivered file either satisfies the agreed condition or it does not. Keep the sample and acceptance rule with the final delivery for later QA.
What should happen before Match Rate data reaches a CRM?
Before Match Rate reaches a CRM, normalize names and addresses, preserve stable identifiers, separate individuals from organizations, and keep the relevant source URL or source label available for audit. Deduplicate only after entity type and affiliation have been checked. Then map the accepted fields to the CRM without overwriting a newer first-party value. Conflicts should route to review, especially when the incoming record would change an account owner, practice location, suppression status, or clinical specialty.
Finish with a dated QA summary that states the requested population, delivered record count, field coverage, excluded rows, and unresolved exceptions. That summary gives sales operations a usable handoff and makes later refreshes comparable. When campaign results arrive, feed bounces, wrong-party calls, and corrected affiliations back into the next build. Match Rate becomes more valuable when source evidence and field outcomes remain connected after delivery.
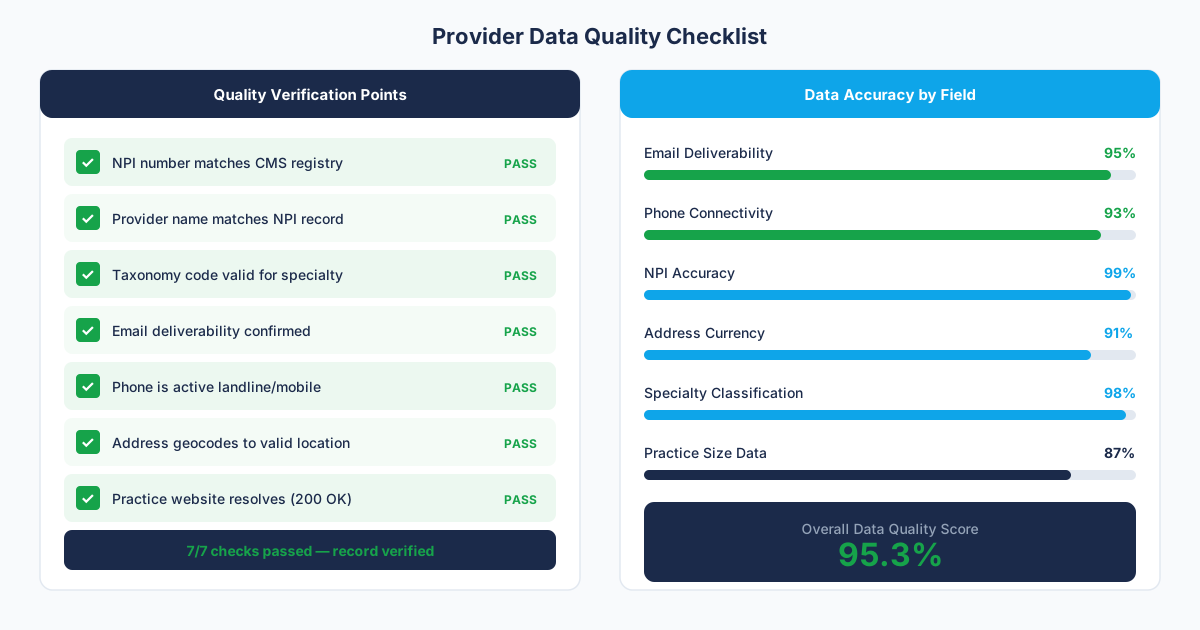
Read the denominator before reading the rate
A match-rate report is useful only when the input population is visible. Record which rows entered the test, which were excluded before matching, how names and addresses were normalized, and whether unresolved candidates stayed in the denominator. Otherwise two vendors can report different rates while describing different tests.
Score identity and enrichment separately. A row can match the correct provider and still return an old practice, a shared phone, or an unsuitable business email. Field-level outcomes show where the workflow works and where manual review remains necessary.
Build the denominator before interpreting the result
Define the eligible input population before calculating the metric. Exclude records that were outside the intended candidates, and report ambiguous inputs separately from genuine failures. A result based only on clean, easy records describes a different problem from one that includes incomplete names, shared addresses, and organizations with several locations.
Keep outcomes by field and entity type. Identity resolution, practice affiliation, email discovery, and phone validation answer different questions. A record can resolve to the correct clinician while its current business contact remains unknown. Collapsing those outcomes into one number hides where research or source coverage needs attention.
Review false acceptance as well as missed records
A successful-looking join can still attach information to the wrong person or practice. Manually inspect accepted rows, rejected rows, and unresolved rows from each segment. Preserve the candidate records and the evidence used for the decision so reviewers can distinguish a conservative miss from a confident but incorrect acceptance.
When comparing runs, freeze the sample and the acceptance rules. Note source dates and any manual interventions. If the population or rules change, label the result as a new test rather than presenting the difference as improvement.
Frequently Asked Questions
What belongs in the input denominator?
Include records that were eligible for the attempted join under the written scope. Report malformed, excluded, and ambiguous inputs separately so the denominator does not change after reviewers see the result.
Why report results by field?
Identity, affiliation, location, email, and phone can resolve independently. Field-level outcomes show whether the source failed to identify the entity or simply lacked a particular enrichment value.
How should unresolved candidates be counted?
Keep unresolved candidates outside accepted and rejected totals, then publish their count beside both. The review queue is an operating outcome and should not disappear into a success percentage.
What makes two tests comparable?
Use the same frozen population, normalization, candidate sources, acceptance rules, and review method. If one of those changes, label the run as a new test and explain the difference.
Why sample accepted records manually?
A plausible join can attach data to the wrong person or practice. Review accepted rows alongside misses and unresolved cases to estimate false acceptance and expose overly permissive rules.
Sources and References
Related Resources
Get the Provider Data You Need
Tell us what you're looking for. We'll build a custom list matched to your target market.
Trusted by healthcare sales teams, medical device companies, and health IT vendors across the US.
How should a match-rate result be reviewed?
Start with the denominator and the acceptance rule. A result is interpretable only when the input population, normalization steps, exact and fuzzy match rules, excluded rows, and unresolved records are visible. Keep successful matches, rejected matches, and ambiguous candidates in separate outputs so a reviewer can inspect the edge cases without changing the reported result.
Compare vendors or methods against the same frozen input and source date. Review field-level correctness after the identity match because a linked record can still carry an old practice, an unsuitable business contact, or the wrong organization relationship. The final report should give accepted and unresolved results the same visibility.
Report uncertainty beside the metric
Publish accepted, rejected, and unresolved outcomes together, with the sample definition and review date. Readers can then see whether a change came from better resolution, a narrower population, or a different treatment of ambiguous records. Keep segment-level results available for diagnosis and later comparison. State who reviewed the sample and where exceptions are stored.